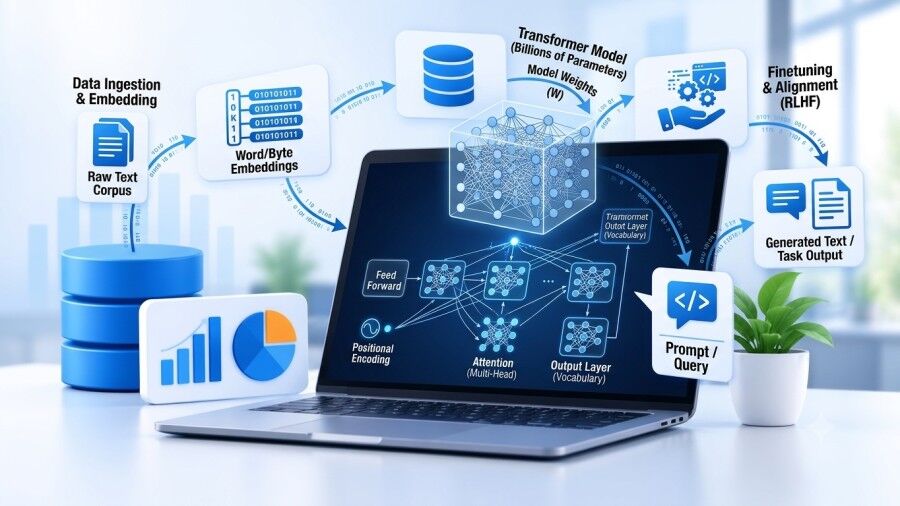
Main layers in plain words:
Data ingestion and cleaning: gather approved data and remove errors or duplicates
Vector database: stores embeddings so the system can search by meaning
RAG: fetches relevant context so answers stay grounded in company data
Guardrails: filter unsafe or uncertain outputs
Integration: connects results to CRM, ERP, or ticketing tools
Monitoring: tracks accuracy, speed, and cost after launch
Skipping any layer often leads to wrong answers or rising costs, so planning each one matters.
Read more: https://www.impressico.com/ ...